The Evolution of Human-AI Collaboration in Problem Solving

People have worked with computing systems on hard problems for decades. In the beginning, machines handled repetitive calculations while people set the goals and checked the results. Over time the division of labor shifted as software grew more capable at spotting patterns in large sets of data.

Early forms of human-computer work

The first practical collaborations often appeared in scientific labs and engineering offices. A researcher might feed raw measurements into a program that returned averages and trends, then the same person would decide whether those numbers pointed to a real effect or just noise. Similar patterns showed up in business when clerks used early spreadsheets to test different pricing models and adjusted the inputs after seeing the outputs.

As machines became faster, the same basic loop remained: the computer proposed an answer, a person reviewed it, and the cycle repeated until the result met practical standards. This approach kept people in charge of judgment calls that rules alone could not settle.

Current ways the two sides combine

Today the most common pattern is called human-in-the-loop processing. The system first scans incoming information and flags items that look unusual or uncertain. A person then looks at those flagged items and supplies a decision. The choice is fed back into the model so it improves on the next round.
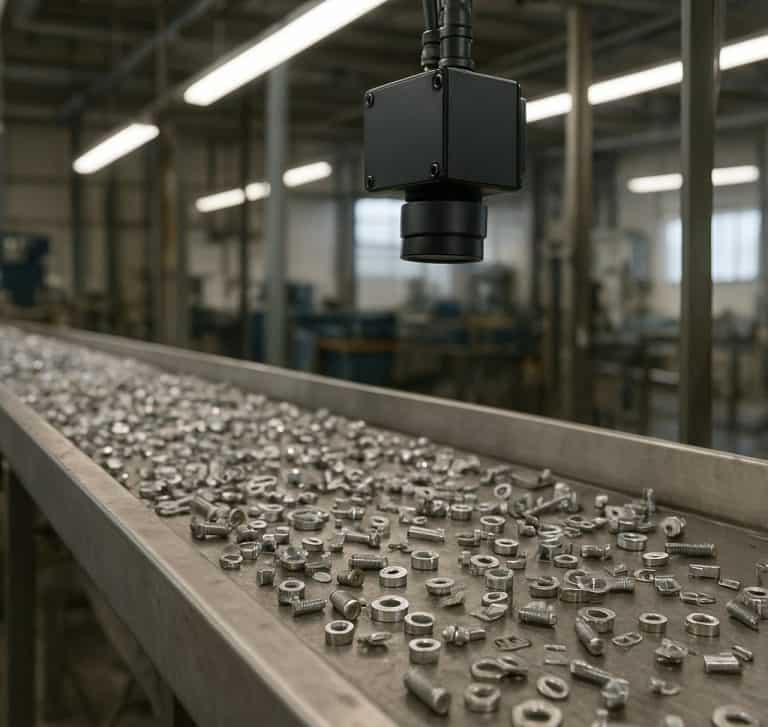
factory conveyor inspection camera setup

Another approach uses active queries. The program selects a small number of examples that would help it learn fastest and asks a person to label them. This reduces the total amount of human time required while still guiding the model toward better performance on the actual task.

A third method keeps separate roles. One part of the system generates many possible solutions, another part ranks them according to past human preferences, and a final reviewer picks or modifies the top option. The ranking step often runs on simple comparison rules that people have already agreed upon.

Practical uses across different fields

In medical imaging a program can mark regions that differ from normal tissue. A radiologist then examines those marks and decides whether they represent a real finding or an artifact. The doctor keeps final responsibility, yet the program reduces the area that must be studied closely.

Manufacturing lines use similar setups for quality checks. Cameras capture images of parts moving on a belt. Software highlights possible defects such as cracks or misalignments. An inspector looks at the highlighted images and confirms or rejects the part. Over weeks the system learns which lighting conditions or angles produce false alarms and stops raising them.

Content platforms apply the same idea at larger scale. Automated filters remove obvious spam or illegal material. Remaining borderline posts go to reviewers who apply company guidelines. Their decisions train the filter to handle more cases without human help.

Current limits and possible next steps

One ongoing difficulty is that models still make errors on edge cases that people would handle without much thought. When the data contains rare events or new patterns, the program may either miss them or flag too many routine items. This increases the workload on human reviewers instead of reducing it.

Another limit appears when the rules themselves change. A policy update in one department can make earlier training data less useful, requiring fresh human labels and slowing progress until enough new examples exist.

Future work is likely to focus on clearer hand-offs between the two sides. Systems may get better at stating how certain they are about each suggestion, so people can spend time only where the uncertainty is high. At the same time, interfaces that let reviewers correct the model with a few clicks rather than full labels could lower the effort needed for each round of improvement.

These adjustments will probably appear first in settings where mistakes carry clear costs, such as safety inspections or regulatory filings. In those areas the value of keeping a person involved remains easy to see even as the software handles more of the routine volume.
Comments Off on The Evolution of Human-AI Collaboration in Problem Solving

Filed under Uncategorized

Business Models Built Around Distributed Online Workforces

Understanding the basics of distributed task systems

These setups break larger projects into small units that people complete from their own locations. A company might split a photo review process into thousands of individual checks, each handled by a separate person who logs in when available. The structure relies on clear instructions that leave little room for interpretation, so results stay consistent across many contributors.

apartment living room work table

Task assignment often happens through platforms that match available work to people based on past performance or simple sign ups. Someone might handle text verification for an hour or two in the evening while another focuses on data entry during a lunch break. This approach lets the overall volume scale without adding permanent staff, though it requires steady inflows of new tasks to keep participants engaged.

The model works best when the work does not need deep context or ongoing discussion between contributors. Simple classification jobs, such as sorting product listings into categories, fit this pattern well. More complex jobs tend to need extra layers of review to catch errors that slip through individual steps.

Contributors usually work without fixed schedules, which means the pool of available labor changes throughout the day. Managers track completion rates and quality scores to decide who receives future tasks. Over time the system learns which instructions produce reliable output and which ones create confusion that slows everything down.

Setting up payment and incentive structures

Payment often takes the form of small amounts per completed unit rather than hourly wages. A person might earn a few cents for each short audio segment transcribed, with totals adding up after several dozen tasks. This per piece approach keeps costs tied directly to output volume.

Some projects add bonuses when a contributor reaches certain quality thresholds over a set period. Others use leaderboards that show relative standing without revealing personal details. These extras can lift participation rates, yet they also create pressure that sometimes leads people to rush and make mistakes.

Not every contributor responds to the same signals. Some treat the work as a way to fill spare time and value flexibility above higher rates. Others seek steady volume and respond more to predictable payouts. Adjusting the mix of rewards helps keep the contributor base from shrinking when tasks become repetitive.

kitchen table device and notebook

Handling day to day operations and issues

Quality control usually depends on overlap, where several people complete the same task and results are compared. Disagreements trigger additional reviews or automatic rejection of the outlier answers. This method adds cost but reduces the chance that bad data moves forward into later stages of a project.

Turnover among contributors can disrupt momentum if too many experienced people leave at once. Clear onboarding materials and quick feedback on early tasks help new arrivals reach useful output faster. Without those supports, error rates stay high until people learn through trial and error.

Communication stays limited by design because most tasks require little discussion. When questions do arise, a help queue or example library answers common points without slowing the main flow. Projects that need more interaction often move those pieces to a smaller group that works under tighter coordination.

Dealing with rules and compliance

Labor regulations differ by country and sometimes by region within a country. What counts as independent work in one place may be viewed as employment elsewhere. Companies therefore track contributor locations and adjust contract language or task availability to stay within local limits.

Tax reporting adds another layer because many contributors treat earnings as supplemental income. Some platforms issue summaries at year end while others leave that responsibility entirely to the individual. The approach chosen affects how attractive the work remains for people who rely on it regularly.

Data privacy rules can restrict which tasks certain contributors see. A contributor in one jurisdiction might not qualify for jobs involving personal information from another region. These limits force managers to segment work carefully rather than offering every task to the full pool.

Keeping the model going over time

Contributor pools change as people move on to other activities or find better paying options. Regular checks on task difficulty and payout levels help spot when interest is dropping before volume falls sharply. Small adjustments to instructions or rewards often restore balance without major redesign.

Long running projects benefit from gradual automation of the easiest subtasks. This leaves contributors with work that still needs human judgment and keeps the remaining tasks from becoming too trivial. The shift also changes cost structures as the mix of human and machine effort evolves.

Sustainability depends on whether the overall economics make sense once all review steps and support costs are included. Some projects find that distributed work stays cheaper than traditional hiring even after those extras. Others discover that certain task types require so much oversight that a smaller dedicated team ends up more practical.

Comments Off on Business Models Built Around Distributed Online Workforces

Filed under Uncategorized

HVAC Repair Through Artificial Intelligence

Artificial intelligence is reshaping how HVAC repairs happen. Diagnostic time shrinks and fixes become more exact, so systems spend less time down. Technicians pull sensor data into AI tools and spot faults early, before a minor glitch turns into a full breakdown. It’s not just faster work. The real change shows when one odd reading gets noticed in time to avoid a whole afternoon of return visits.

That kind of early notice keeps the whole crew from juggling extra stops that pile up by the end of the day.

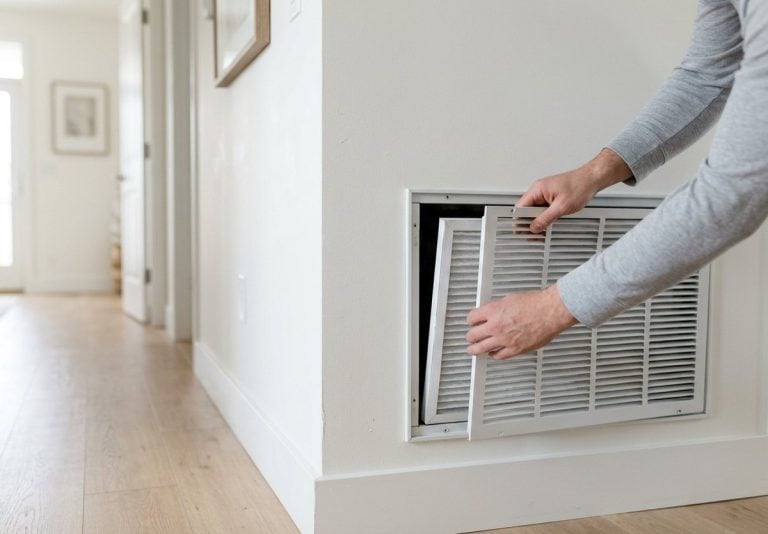
hands slide clean new white pleated

How AI Diagnostics Get Used

Today’s systems take live readings from temperature sensors and pressure gauges. They line those numbers up against past performance and flag anything off within minutes. Repair crews then get a short list of likely causes, which cuts down on guesswork testing.

You see the shift on normal service days. A tech who once pulled panels and swapped parts to narrow the problem now starts with a targeted list. Diagnostic time often falls from two hours to under half an hour. Equipment lasts longer when small issues are handled early. Repeat calls drop because the real cause gets fixed the first time, and that changes how the day flows.

Moving Toward Predictive Maintenance

AI models look at usage patterns and conditions to predict when parts will wear out. They build maintenance plans around actual run hours rather than set dates on the calendar. That avoids service visits that aren’t needed while still catching parts that are aging quicker than usual.

Property managers watch results on dashboards that show expected failure dates and next steps. Teams handle the right fixes at the right moment so systems hold up through busy periods. The payoff stands out clearest in buildings with uneven loads across the year. A unit left off for weeks might still need motor work because of how hard it ran the last time it was on.

The same pattern shows up when loads change without warning and force a part to work harder than expected.

Speeding Up How Techs Pick Up Skills

AI tools give technicians repair steps matched to the exact model on the job. Visual guides show wiring routes and part locations right on a tablet or headset. Newer techs reach steady output sooner since the software supplies knowledge that used to take years on the job from places like BPI.

It fills gaps that only come from seeing the same issue repeat across different setups.

Experienced techs lean on the same tools to double-check tricky calls and log every detail for warranty work. Human know-how plus machine output leads to steadier results from one site to the next. And sometimes the help is as simple as a second look at an old wiring diagram.

Linking HVAC to Other Building Systems

These platforms tie HVAC readings into controls for lighting and security. When a fault shows up, the system can shift related equipment to hold comfort levels during repairs. That coordination cuts down on complaints and keeps sensitive spots from swinging in temperature.

Service logs feed straight back into the model, so predictions get better over time. Fault detection improves and emergency calls start to thin out.

Watching Results After Setup

Facilities keep spotting small patterns long after the first fixes. A damper that sticks only when humidity rises or a sensor that shifts after power changes begins to appear in the records. Fixing those early adds reliability that fixed schedules often miss.

Getting It Running and Measuring the Gains

Most places finish the integration in four to six weeks. Setup means linking current sensors to the software and showing staff how the interface works. After the first month, managers usually notice fewer unplanned repairs. By month three, energy use drops and uptime improves.

Day-to-day monitoring takes little staff time since the system only flags what needs attention. Annual agreements handle updates and remote help so the platform stays current without big upfront costs.

For facilities that want clear results from AI-driven HVAC work, Cobra HVAC provides the hardware and training. Their focus stays on cutting service calls and energy use within set periods.

Where Human Judgment Still Matters

Strong data doesn’t end the need for experience. Some jobs still call for an on-site call on whether a flagged part should be swapped right then. The software narrows choices but leaves that final decision to the tech. Two explanations can fit the same reading, and only someone who’s seen the equipment before knows which one matches what’s actually there.

Comments Off on HVAC Repair Through Artificial Intelligence

Filed under Uncategorized

How Crowdsourcing Supports Data Collection in Academic Studies

Crowdsourcing lets researchers pull in data from many people at once instead of running every session in a lab or sending out paper forms to a limited group. A team studying daily habits might ask contributors to note what they ate at lunch or how long they walked, all through simple online forms. This spreads the work across hundreds of participants who log in from home or a coffee shop, often completing short tasks in a few minutes each.

What crowdsourcing offers academic work

The main advantage shows up when a project needs volume. One person can only answer so many questions in a day, but a distributed group can label thousands of photos or transcribe short audio clips over the same period. Researchers have used this for mapping local weather patterns by having contributors report conditions from their own neighborhoods. The approach works best when the task breaks into small, repeatable pieces rather than long essays or complex judgments that require special training.

Some studies combine crowdsourced data with smaller sets gathered in controlled settings. The online portion supplies breadth while the lab portion supplies depth on a few cases. Results can vary because contributors differ in attention and background, so the method suits projects where patterns emerge from many observations rather than precise measurements from a few experts.

laptop mug table daylight setup

Common ways to find and sign up contributors

Recruitment often starts with existing online task sites where people already look for short paid work. Researchers post a description of the task, set a small payment per completed item, and include screening questions to filter for basic language skills or location. Another route uses university mailing lists or social media groups tied to the topic, which can bring in participants who have a direct interest, such as parents reporting on child development milestones.

Clear instructions matter more than fancy graphics. A task that asks contributors to count cars in a street photo works better when it shows two examples of correct counts and two examples of mistakes. Payment rates stay modest because most contributors treat the work as occasional rather than full time. Response speed changes with time of day and day of week, so spreading postings over several days can even out the flow of completed tasks.

Steps to check and improve the information collected

Raw submissions contain errors, so most projects build in checks before the data enters the final set. One common step mixes a few known correct answers into the stream of tasks. If a contributor misses too many of these test items, their other answers get set aside. Another step sends the same item to several different people and keeps only the answers where most agree.

Simple rules help too. A form that collects numerical ratings can flag responses that always pick the same number or finish in under ten seconds. When the task involves open text, researchers sometimes read a random sample themselves to spot patterns like copied phrases or off-topic replies. These checks do not remove every problem, yet they cut down the share of unusable entries enough for many studies to proceed.

Keeping participant information safe and studies ethical

Contributors need to know what will happen with their answers before they start. A short consent statement at the top of the task explains the purpose in plain language and notes whether names or other identifiers will be stored. Data should be stripped of direct links to individuals as soon as possible, and files kept on secure drives rather than shared drives open to a whole department.

Privacy questions arise when tasks touch on sensitive topics such as health symptoms or political views. In those cases researchers often limit the questions to general categories and avoid any follow-up that could identify someone. Rules differ by country and by institution, so the safest route is to review the planned questions against standard guidelines for human subjects work and adjust wording or skip items that cross into personal territory. Over time these steps build trust so that contributors continue to accept tasks from academic sources.

Comments Off on How Crowdsourcing Supports Data Collection in Academic Studies

Filed under Uncategorized